Browsers were designed to fetch and display documents. The idea that the same software, sandboxed, portable, running on a decade-old laptop in a coffee shop, can now reconstruct images with neural networks sounds, on its face, absurd. It works anyway, and the distance between "absurd" and "works" is where all the interesting engineering lives. This is a tour of that distance: what actually happens when you drop an image into a local AI tool, and every workaround the browser's constraints forced us into.
The network is just a file
Start with the mental model most people lack. A trained neural network is, physically, a large file of numbers (weights, arranged in layers). It contains no code in the traditional sense; it is data that describes how to transform other data. That distinction matters because files are something browsers have always been good at handling. When you visit a local AI tool for the first time, the browser downloads this file the way it would download any asset, and stores it in a cache so subsequent visits skip the download.
This is the first deliberate design choice: the file arrives once, then your images never do the reverse. There is no symmetry in the traffic. Dozens of megabytes flow down to you; zero bytes of your imagery flow up. Watching a network inspector during heavy use makes the architecture viscerally clear: the request log is completely quiet while your photos are being processed.
Where the math runs: the GPU enters the chat
A neural network pass is embarrassingly parallel: millions of small multiplications and additions with no particular order between them. CPUs handle this, but slowly, because a general-purpose processor has a modest number of cores. GPUs have thousands of small cores built for exactly this shape of work, originally matrix math for graphics rendering, which is arithmetically identical to what neural networks need.
Modern browsers expose that hardware through GPU compute APIs. This is the single development that made browser AI practical. Under WebGPU, the current generation, the browser hands the network file and your image data to the graphics driver as raw buffers and lets the GPU chew through them. The same photograph that takes minutes on a pure-CPU path completes in seconds on GPU. When WebGPU is unavailable, the fallback is WebAssembly: a portable binary format that runs near-native-speed code in the browser, multithreaded across CPU cores. Slower, but everywhere.
Workaround one: tiling, because memory is finite
A 12-megapixel photo upscaled 4× produces a 192-megapixel intermediate representation during processing. Graphics memory on an ordinary laptop is shared with everything else your machine is doing, from the browser itself to other tabs to the operating system. Holding the entire computation at once is not reliably possible. The workaround is tiling: split the image into overlapping patches, process each patch through the network independently, and stitch the results back together.
Tiling creates its own problem. Neurons at a tile's border only see half their context, so their output differs slightly from what the same pixels would produce mid-tile, and naïve stitching shows those disagreements as visible seams. The fixes are unglamorous but effective: substantial overlap between tiles so border regions can be cross-faded, consistent normalization so every tile sees identical statistics, and blending windows that distribute the error over hundreds of pixels where the eye cannot find it.
Workaround two: keeping the page responsive
JavaScript shares a thread with the page. If that thread is busy multiplying matrices for three seconds, clicks do not register, scrolling stutters, and the browser eventually asks the user whether the page has crashed. The workaround is the worker: a separate thread that owns the computation entirely and communicates with the page only in messages. The page stays a polite, responsive document; the worker becomes a compute server living inside the tab.
Progress reporting rides the same message channel. Because processing happens in tiles and stages, the worker can post genuine progress: not a decorative spinner, but an actual percentage derived from work completed. The chime that plays when your image finishes is the same message pathway, which is also why the browser can notify you even when the tab is in the background.
Workaround three: the first-run wait
The network file has to come from somewhere, and a cold first visit pays for it in download time. Three mitigations stack up. The file is cached in the browser's persistent storage, so the cost is paid once per device, not once per session. Downloads stream with visible progress rather than a frozen page. And on return visits, the cache is verified rather than redownloaded, a quick hash check instead of a multi-second transfer.
After your first visit, wait for the page to fully load, then disconnect from the network. Every tool still works. That is the moment the architecture stops being a claim and becomes something you have verified yourself.
Workaround four: detecting what the hardware can do
Browser, operating system, and hardware form a combinatorial space of capability. The detection layer asks a stack of questions in order: is a modern GPU compute API exposed and does initialization succeed, does the device have enough memory for the working set, did the first real inference complete without the driver crashing (drivers lie; some report support they cannot deliver). Only when every answer comes back positive does the tool commit to GPU acceleration; otherwise it silently drops to the CPU path, which is slower but dependable.
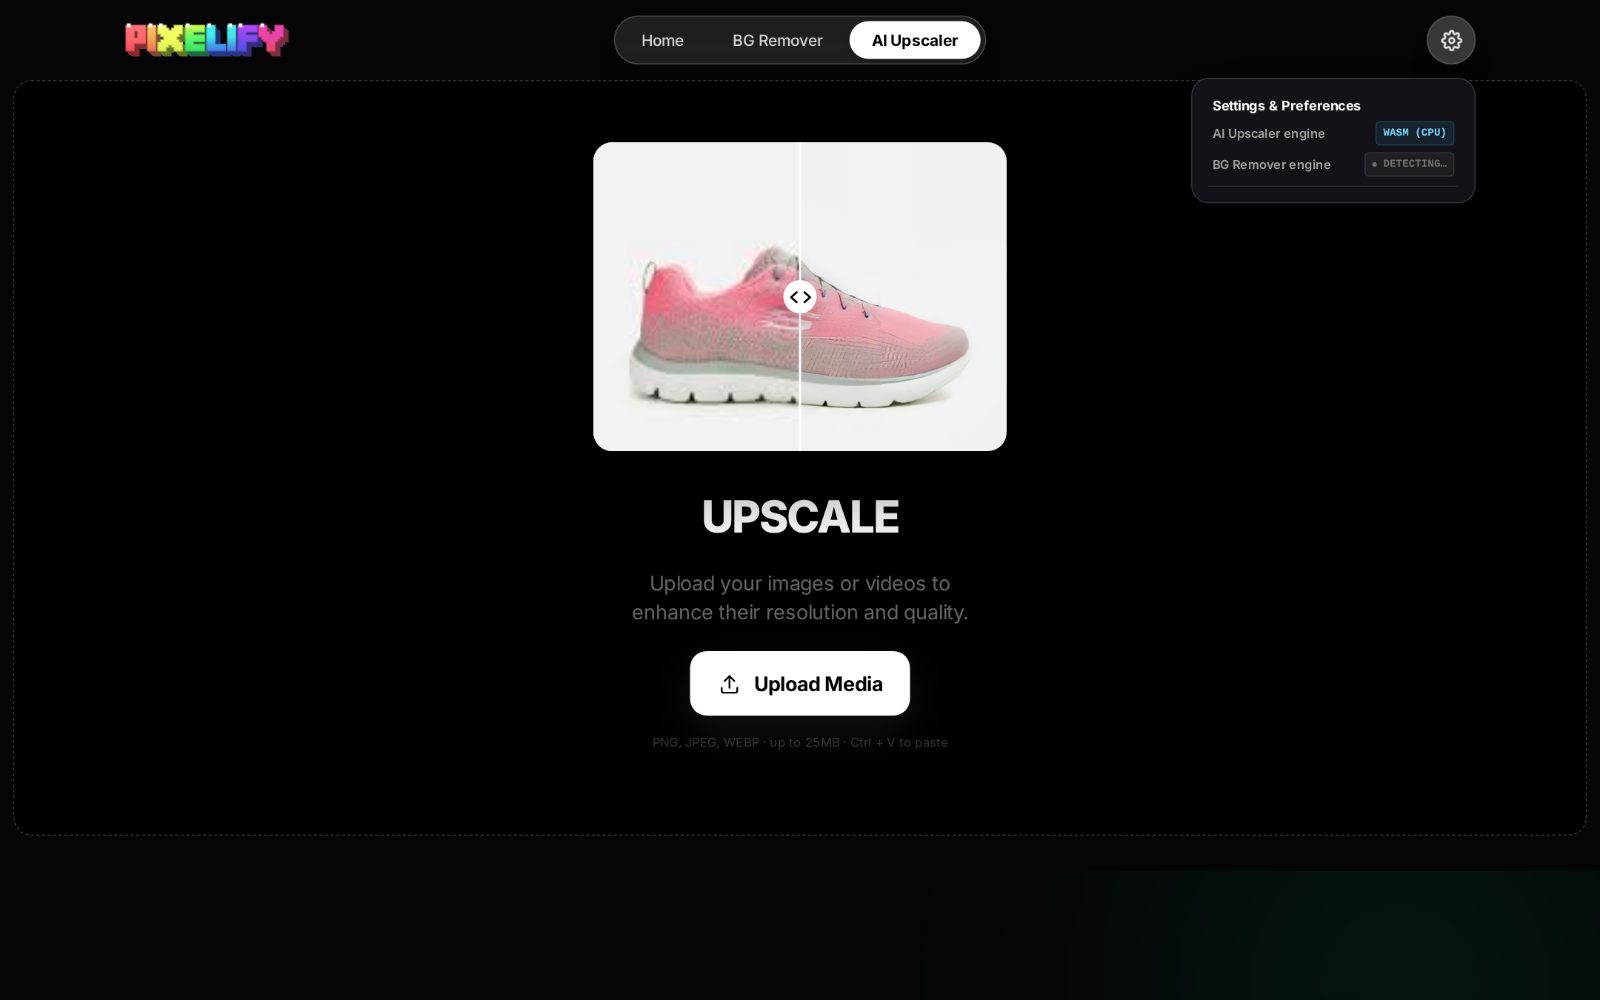
This decision is deliberately visible in the product. The settings panel reports the live engine for each tool, read back from the runtime rather than assumed from feature detection. Users on the CPU path see exactly that, users on the GPU path see acceleration confirmed, and bug reports arrive with a diagnostic already attached. Transparency here is not a privacy gesture; it is an engineering one.
Why it will only get faster
Every layer of this stack is on an improving trajectory. GPU compute APIs are getting broader driver support and better shader compilation. Browser runtimes are optimizing their tensor operations. Hardware vendors ship more capable mobile and laptop GPUs each year. And the network files themselves shrink as distillation techniques improve, producing smaller networks that retain most of the quality of their larger siblings. The workaround list above will not disappear, but its cost to the user trends toward zero.
The deeper point is architectural, not technical. The browser turned out to be a surprisingly good home for AI workloads: it is already installed everywhere, already sandboxed, already gets the security model right, and, uniquely among software platforms, ships its own updates to billions of devices without a download prompt. Software that must run on your machine without trusting its operator is exactly what browsers were built to be. Local AI did not force its way into the browser. The browser was waiting for it.